DecisionTune 1.0: a 395M decision model. $20 of compute. Clean data.
29.57 on Decision Index 0.2.1
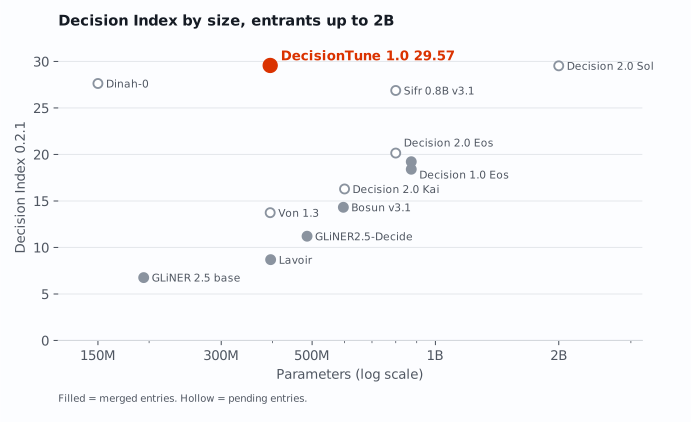
Measured on one full run. On Decision Index, the highest score we can see under 500M parameters (results). On JevBench, it is not (JevBench).
The run is complete. Nothing was truncated. No options were removed. Requests over the context limit were refused, not cut.
Try it
Coming soon: pip package and live demo.
Updates will land here and at hotin.ai.
Results
Under 500M parameters, the highest other entry we can see is Dinah-0 at 27.63 (150M, pending, not merged). DecisionTune 1.0 is 1.94 points above it. Decision 2.0 Sol (2B) scores 29.53 (pending): level with DecisionTune 1.0, at five times the size. Board as of 2026-10-03.
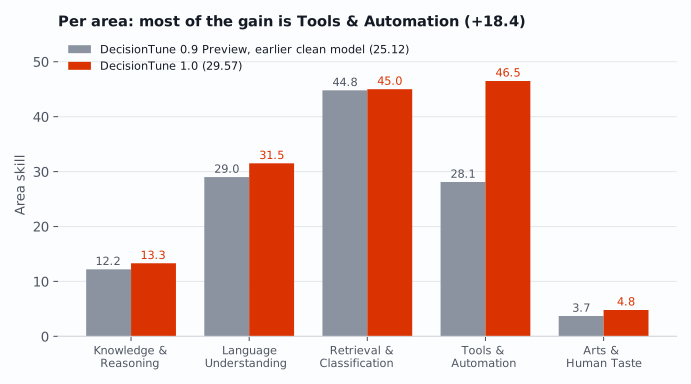
Per area (skill)
| Area | 1.0 | 0.9 Preview | Change | Dinah-0 |
|---|---|---|---|---|
| Knowledge & Reasoning | 13.3 | 12.2 | +1.1 | 19.1 |
| Language Understanding | 31.5 | 29.0 | +2.5 | 22.7 |
| Retrieval & Classification | 45.0 | 44.8 | +0.2 | 47.8 |
| Tools & Automation | 46.5 | 28.1 | +18.4 | 37.9 |
| Arts & Human Taste | 4.8 | 3.7 | +1.1 | 3.5 |
Dinah-0 is ahead in two areas (Knowledge & Reasoning, Retrieval & Classification). Nine benchmarks score 0.0, including ANLI, GPQA Diamond, ChessBench and HLE.
JevBench
JevBench is a separate public benchmark of typed decisions. We ran its public set of 231 tasks on our own machine. DecisionTune 1.0 answers 55.0% correctly (127 of 231, 95% CI 48.1 to 61.5). DecisionTune 0.9 Preview answers 51.5% (119 of 231). The gap is 3.5 points, within noise.
On JevBench, DecisionTune 1.0 is not at the top of its size class. Public results for models under 500M parameters range from 22.1% to 62.8%. At least seven of them are above DecisionTune 1.0.
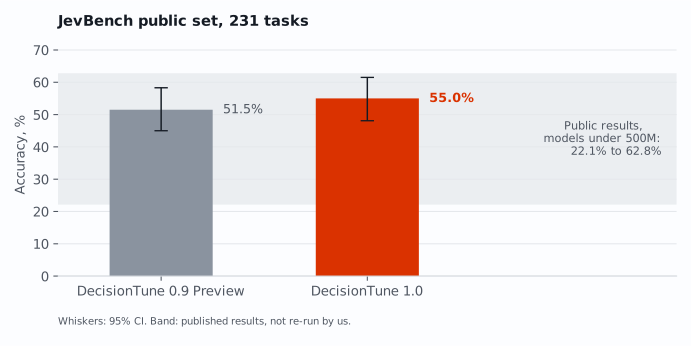
18 of the 231 tasks are rating questions. DecisionTune never trained on rating questions. It answers them zero-shot, by choosing among the level texts: 9 of 18 correct, where chance is about 4.4. This is the public set only, not a JevBench board score. We copied the peer results from the benchmark's published files. We did not run them again.
Cost
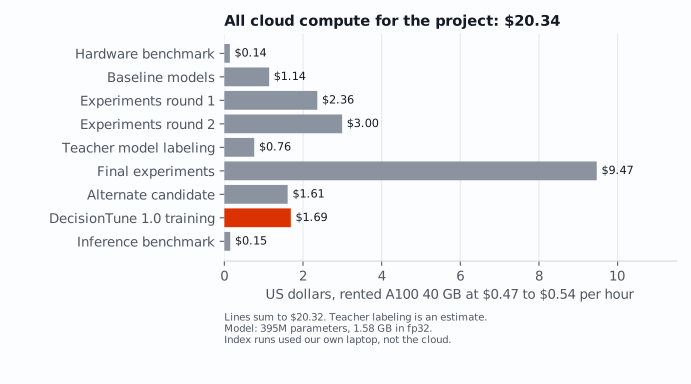
All cloud compute for the project cost $20.34 on rented A100s. Training DecisionTune 1.0 itself cost $1.69.
How we built it
- We started from ModernBERT-large and added a 4 KB scoring head.
- We checked every license first. We kept a dataset only when its publisher tag is permissive. We dropped anything marked non-commercial, share-alike or research-only.
- A $0.14 speed test moved all training off our laptop. We trained on rented A100s at $0.47 to $0.54 per hour.
- Part of its training learned from a larger open model, Clef-Flash (Cloudflare/clef-flash, Apache-2.0). It labeled 93,303 training units for about $0.76 (estimate). We used its answers on 8 datasets.
- We found shortcuts in our own training data and our own scorer. We fixed them and measured again.
The full build story comes in a launch write-up.
Honesty
- Test-informed plan. We ran the full index six times during development. We designed several fixes after we saw index results. We used no index rows, labels or option texts as training data.
- Contamination audit. Our overlap check dropped 0 of 270,624 training rows. Caveats: 47 rows overlap our own practice set, not the index. ContractNLI rows share boilerplate with test contracts (max Jaccard 0.482, under the 0.5 line). One older data pool was not scanned again.
- GSM8K. In the index, the GSM8K gold answer is always the center option. With GSM8K at our starting model's value, DecisionTune 1.0 scores 28.48. We report both numbers.
- One seed, one run. We have no second-seed result yet. Latency was measured on our laptop, not on the board's hardware.
- Product checks (ours, not the board). JevBench public set: see above. LoRA adapter utility: mean 72.5 vs 72.0 for DecisionTune 0.9 Preview (one seed). Held-out product test: -3.7 vs DecisionTune 0.9 Preview [-5.5, -1.8].
The full list of our mistakes comes with the launch write-up.